Skip to content

Software & AI engineer

Jeremy Yao

I take LLM applications from prototype to production with evaluation, caching, and regression tests.

Applied AI / LLM Evaluation & Reliability / Agent Systems

Full-time from January 2027

Scroll to discover

Lines join projects that share a theme.

By the numbers

Numbers with the method attached

  • 82.3% to 94.3%

    spec pass rate after owner-approved rules (McNemar p < 0.001)

    JiangNan AI Concierge
  • 0/50

    prompt-injection attacks succeeded in a preregistered 70-case red-team slice

    JiangNan AI Concierge
  • 500 to 200 ms

    p95 latency on AI-backed endpoints

    Mole AI

About / Jeremy Yao

I build AI systems that survive beyond the demo: model evaluation, agent reliability, and the production backends behind them. I care about what happens when things fail, and how to make them work again.

Location
Boston, MA
Education
M.S. Computer Science, Northeastern, Dec 2026
Availability
Full-time from January 2027

Featured project

JiangNan AI Concierge

01 / AI Engineer · Contract / Jul 2025 – Present

JiangNan AI Concierge: how a guest question is answered, and how the answers are measuredAn illustrative guest question in Chinese about peanuts in a dish goes through language routing, the menu (100+ dishes) and service policies (90+ validated records), the model chosen in a three-model bake-off (0 of 60 hallucination or allergen-critical failures on the initial test set), and an allergen safeguard that can escalate to staff, then gets an answer in Chinese. Measured by 300 bilingual eval cases: spec pass rate 82.3% to 94.3% after owner-approved rules (McNemar p below 0.001), 0 unsafe allergen answers; a judge audited against 100 human labels, kappa 0.82 between draft and final judge over 600 verdicts; and a red team where 0 of 50 prompt-injection attacks succeeded.ILLUSTRATIVE EXAMPLE〔菜名〕里有花生吗?我对花生过敏。Does [dish] contain peanuts? I'm allergic.Language routingChinese in, Chinese out2Menu100+ dishesService policies90+ validated records1LLM, chosen in a 3-model bake-off0/60 hallucination or allergen-critical failureson the initial test set3Allergen safeguardchecks before answeringStaffescalation2按菜单记录,〔菜名〕〔含有/不含〕花生。如需再确认,我会转给工作人员。Per the menu record, [dish] [does / doesn't] contain peanuts.For more certainty, I'll pass this to staff.MEASURED BY300 bilingual eval cases82.3% → 94.3%spec pass rate after owner-approved rulesMcNemar p < 0.001 · 0 unsafe allergen answers4Judge audit0.82κ, draft vs final judge5Red team0/50injections succeeded6
  1. 01

    Grounded in the house rules

    The concierge answers from the restaurant's own menu and service policies: 100+ dishes and 90+ validated policy records.

  2. 02

    Language routing and allergen safeguards

    Guests write in English or Chinese and get answers in their language, with allergen safeguards and escalation to staff. It served 1K conversations a month.

  3. 03

    A three-model bake-off

    A cheaper model answered 7 of 30 Chinese prompts in English and made an unsafe allergen claim, so it lost. The chosen model had 0 of 60 hallucination or allergen-critical failures on the initial test set.

  4. 04

    300 bilingual eval cases

    60 authored cases and 240 generated from the knowledge base with price and allergen checks. Owner-approved rules lifted spec pass rate from 82.3% to 94.3% (McNemar p < 0.001), with 0 unsafe allergen answers.

  5. 05

    Auditing the judge

    Cache-stable prefixes cut judge cost to about 1/8. Against 100 human labels the judge never passed a bad answer but over-flagged (1 of 8 hallucination flags held up), so pass rates count as conservative. A draft judge matched the final at κ = 0.82 over 600 verdicts.

  6. 06

    Red team, and guards that had to earn their place

    0 of 50 prompt-injection attacks succeeded in a preregistered 70-case slice. The v1 guards caused 9 critical allergy regressions on 240 paired controls; v2 fixed them, and guards stayed off until proven useful.

Featured project

HiveMind

02 / Open-source contributor / Aug 2026 – Present

HiveMind is the AgentFlow multi-agent runtime (1.1K GitHub stars). I authored 3 merged PRs (#92, #93, #94) for model fallback, reasoning persistence, and multimodal attachments, across Python, Spring Boot, PostgreSQL, and Next.js.

HiveMind: how a request survives a failing modelModel routing sends a request to the first model in an ordered fallback list. The first model streams text, reasoning, and attachment events as separate SSE event types, then stalls. Rate limits, 5xx responses, timeouts, and connection errors are retried; an invalid 4xx fails fast. Retries are bounded and every attempt is traced with a structured log and an OpenTelemetry counter. When retries run out, the request moves to the next model in order, which answers. After a reconnect, the client draft is reconciled with persisted PostgreSQL messages, and stored reasoning is not passed into later model context. Model IDs and the attempt bound follow the router configuration in PR #92: max_attempts_per_model 2 here, default 1, maximum 5.ClientNext.js, SSEModel routeropenai/gpt-4o-mini → openai/gpt-4o1openai/gpt-4o-mini · attempt 1 of 2textreasoningattachmentstimeout2Retryrate limits (429) · 5xxtimeouts (408/409) · connectionFail fastother 4xx3Bounded retriesattempt 2 of 2 · 5xxeach attempt: structured log + OpenTelemetry counter4attempts exhausted: next model in orderopenai/gpt-4o · attempt 1 of 2streams text, reasoning, attachmentsok5After a reconnectclient draftPostgreSQL messagesreconciled, state restoredstored reasoninglater model context6Config from PR #92: max_attempts_per_model 2 (default 1, max 5)retry_on timeout · rate_limit · server_error · connection
  1. 01

    Request routed

    Model routing sends each request to the first model in an ordered fallback list.

  2. 02

    Streaming, separated

    Text, reasoning, and attachment events travel as separate SSE event types.

  3. 03

    Failure classified

    Rate limits, 5xx responses, timeouts, and connection errors are retryable; an invalid 4xx fails fast.

  4. 04

    Bounded retry, traced

    Retries are bounded, and every attempt is traced with structured logs and OpenTelemetry counters.

  5. 05

    Ordered fallback

    When retries run out, the request moves to the next model in order.

  6. 06

    Recovered after reconnect

    After a reconnect, live client drafts are reconciled with persisted PostgreSQL messages to restore state, without passing stored reasoning into subsequent model context.

Selected work

What I built and how I measured it.

Junior software engineer · Remote · Aug 2023 – Aug 2024

Mole AI

Cut p95 latency on AI-backed endpoints by running independent AI-service calls concurrently, and built OAuth 2.0 login with JWT sessions for web and mobile.

  • 500 to 200 msp95 latency on AI-backed endpoints
  • −30%MongoDB query time on high-frequency workloads
  • Co-founder & developer · Jun 2023 – Present

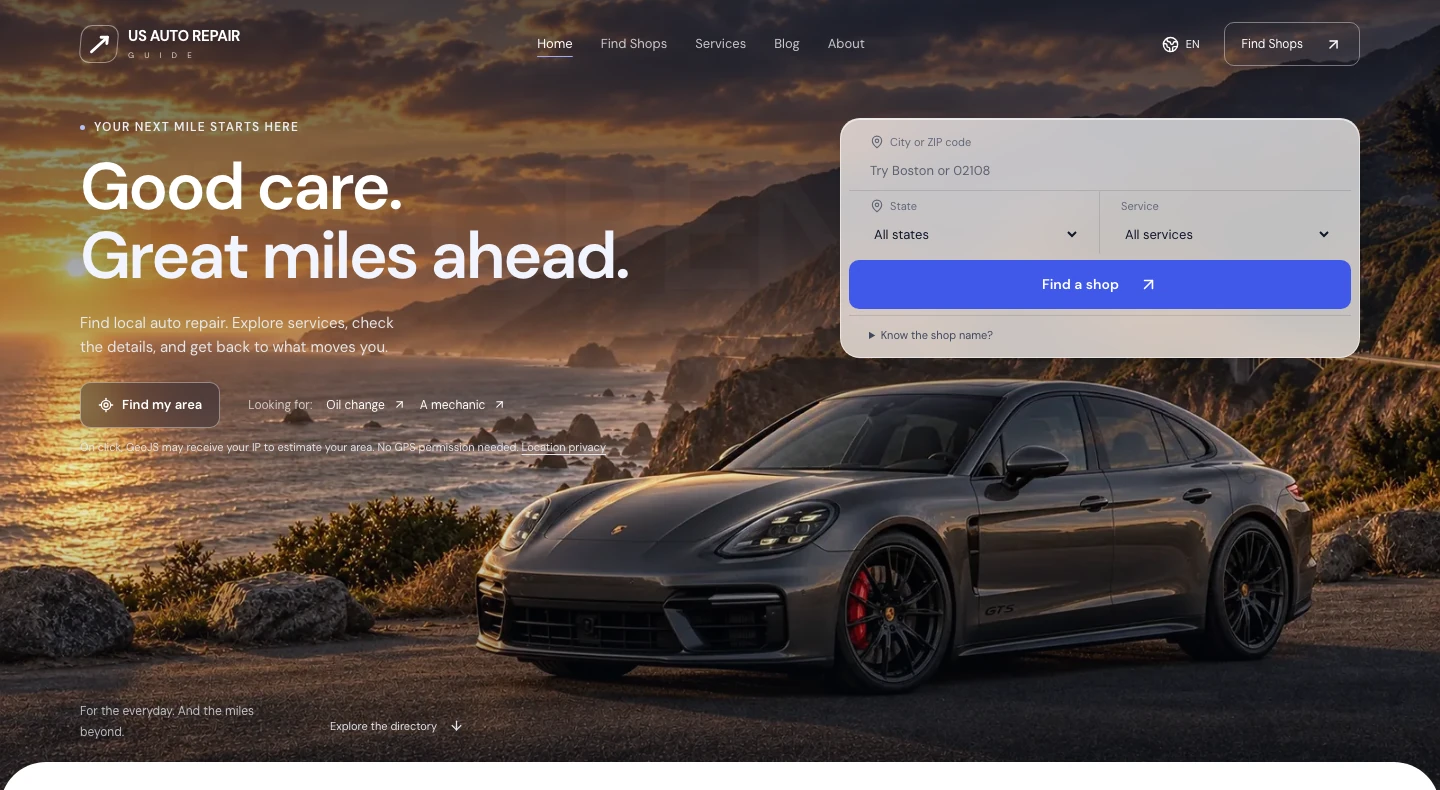
    US Auto Repair Guide

    A nationwide directory of 200K+ auto-repair shops across 50 states, with bilingual search by city, ZIP code, and service type.

    2.5 s to 1.3 spage load (−48%) with indexed, paginated MySQL search

    US Auto Repair Guide homepage with city, state and service search over a coastal road scene
  • Built and launched · Aug 2026 – Present

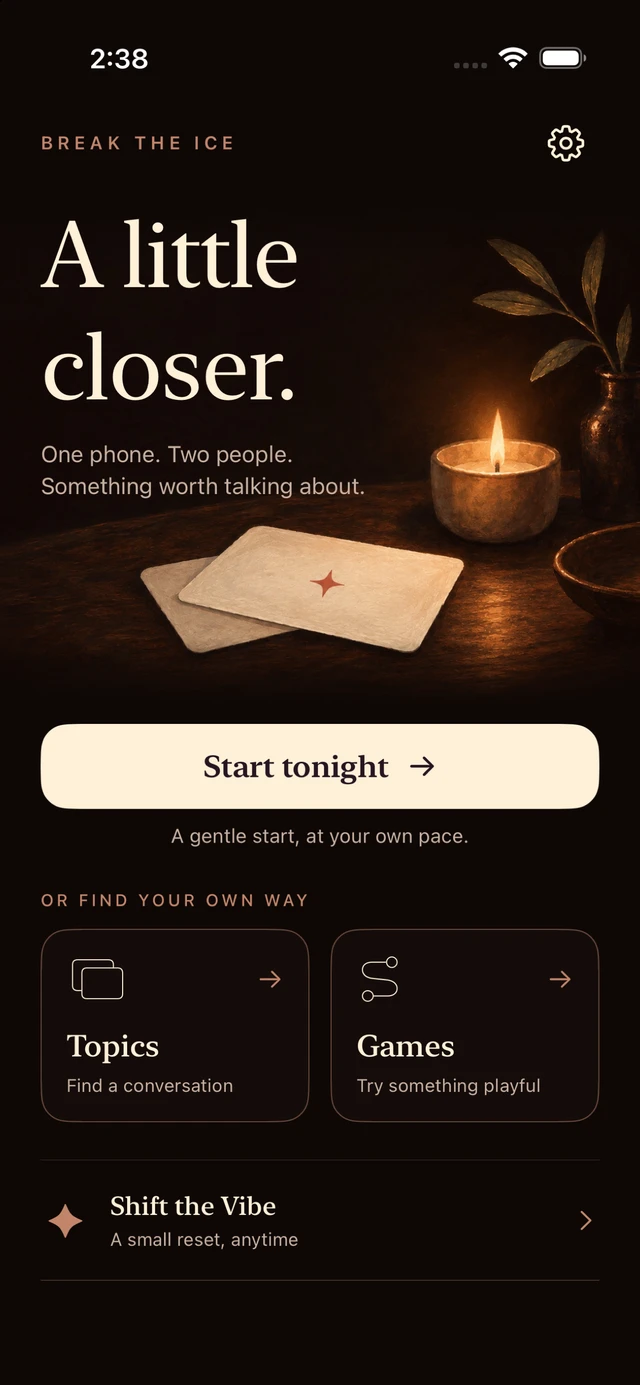
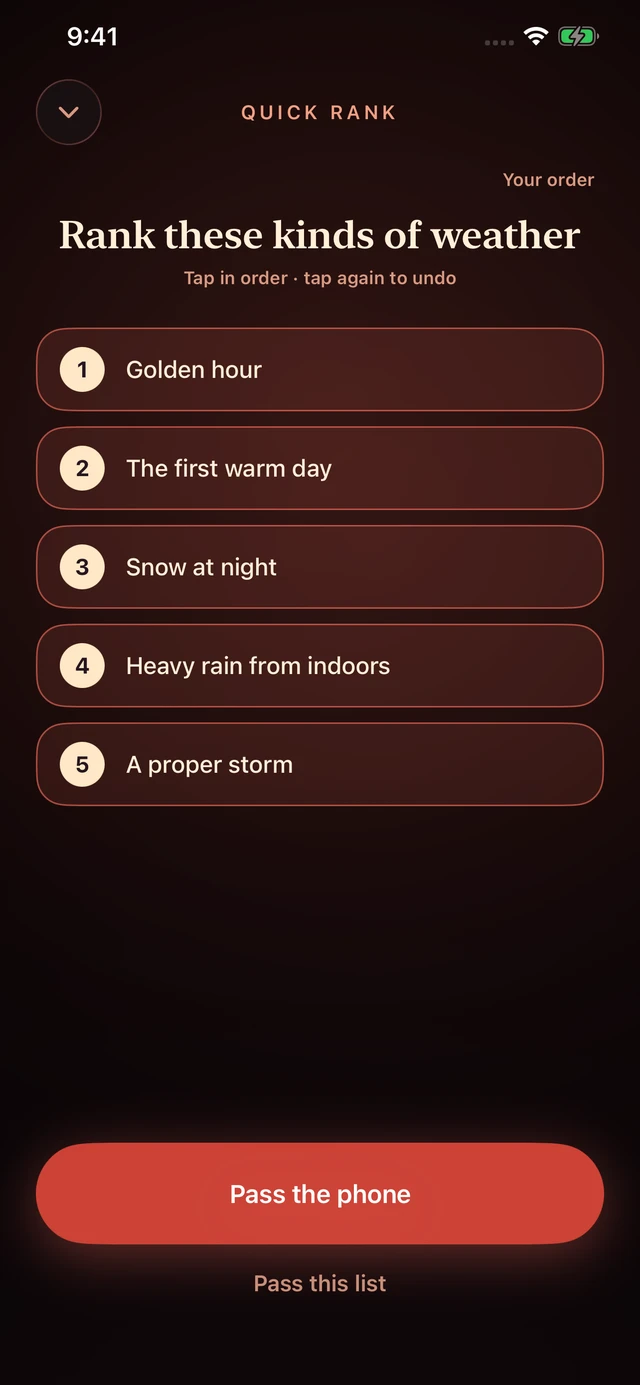
    Break the Ice: Date Night

    A SwiftUI app on the App Store with five pass-the-phone date-night games, on-device personalization, safety filtering, and no repeated prompts across sessions.

    60user-context scenarios covered by XCTest

    Break the Ice app home screen with Start tonight, Topics, and Games
    Quick Rank game with a ranked weather list and Pass the phone action
  • Prototype · Jan 2026

    Restaurant Reservation Agent

    A human-in-the-loop LangGraph booking flow for a POS without an API: the agent writes only to a staff-confirmed request ledger, and the guest approves every write.

    0invariant violations across 272 conversations

  • Research assistant · UMass Boston · Oct 2022 – Jul 2023

    FORESEE: Conversational Dietary Recall

    Usability and privacy studies of a Google Home and Alexa dietary-recall assistant for older adults.

    80+System Usability Scale (SUS) score

Experience

Roles and education

  1. Jul 2025 – Present

    AI Engineer (Contract), JTBC Inc.

    JiangNan Boston

  2. Aug 2026 – Present

    Open-Source Contributor, HiveMind

    AgentFlow multi-agent runtime

  3. Jun 2023 – Present

    Co-Founder & Developer, US Auto Repair Guide

  4. Aug 2023 – Aug 2024

    Junior Software Engineer, Mole AI

    Remote

  5. Oct 2022 – Jul 2023

    Research Assistant, UMass Boston

    FORESEE: Conversational Dietary Recall

Education

  • Sep 2024 – Dec 2026 (expected)

    M.S. in Computer Science, Northeastern University

  • Sep 2019 – May 2023

    B.S. in Computer Science, University of Massachusetts Boston

Contact

Hiring for applied AI or LLM reliability? Let’s talk.

Boston, MA

Looking for

  • Backend, AI infrastructure, or applied AI engineering roles
  • Boston or New York; remote works; open to relocating for the right role
  • Full-time from January 2027